Bridging Machine Learning Research and Production

Mohammad Abdollahi1
1Thomson Reuters, Toronto, Canada
moham98@yorku.ca
Agentic AI LLM Reasoning NLP MLOps
▸AI/ML Research Engineer · research → production
Abdollahi

Mohammad

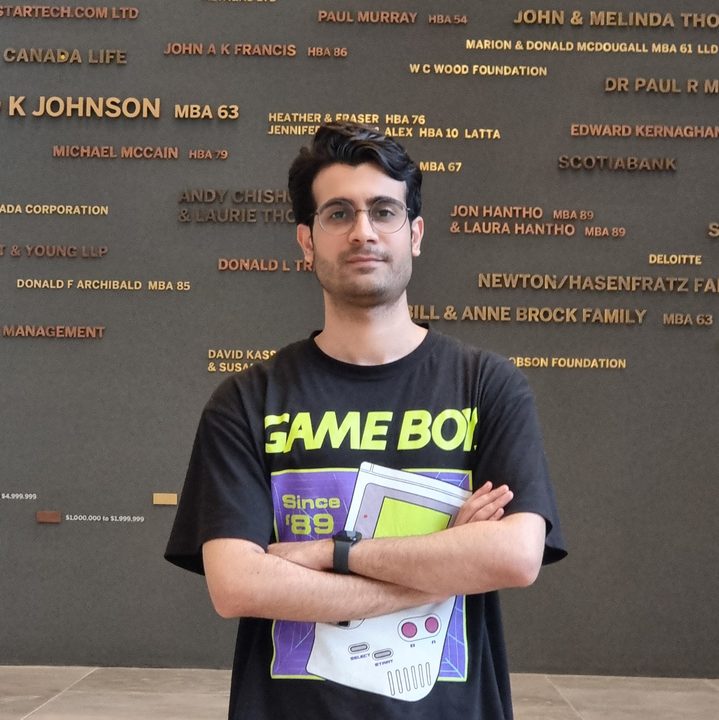
Portrait of Mohammad Abdollahi
▸ NOW

Senior AI/ML Research Engineer at Thomson Reuters, bridging the gap between ML research and production.

Initialize contact
01

About

// profile

I'm a Senior AI/ML Research Engineer at Thomson Reuters with 6+ years across Machine Learning, NLP, Large Language Models, Agentic AI and MLOps. I was fortunate to complete my graduate studies at York University (Toronto, Canada) under the supervision of Prof. Hadi Hemmati (Google).

My research focuses on LLM reasoning and Agentic AI for software engineering. I work on the theoretical foundations of AI to build intelligent, autonomous coding agents that solve complex software tasks.

I design scalable, end-to-end ML systems that close the gap between research and production. I don't just train models; I challenge them. My interest lives in the edge cases and the "impossible" problems where standard algorithms break down.

Keywords: Agentic AI; LLM Reasoning; NLP; MLOps

6+
Years in ML & AI
Multiple
Research papers in top-tier venues
02

Experience

// execution history
01
Senior AI/ML Research Engineer
Thomson Reuters — Toronto, CA
Visit
May 2026 — Present
02
Machine Learning Engineer
Arteria AI — Toronto, CA
Visit
Sep 2025 — Jan 2026
03
Machine Learning Engineer
Digikala.com
Visit
Dec 2021 — Dec 2024
04
Data Scientist
Snappfood
Visit
May 2021 — Dec 2021
05
Software Engineer
Virgool
Visit
Jul 2019 — Aug 2020
03

Stack

// installed modules

Languages

Python Go C / C++ Java JavaScript R

ML & AI

PyTorch TensorFlow HuggingFace OpenAI LangChain LangGraph Scikit-learn XGBoost Agentic AI RAG vLLM Ollama LMCache

Infrastructure & MLOps

Docker Kubernetes AWS GCP Kafka Airflow MLflow RabbitMQ Celery Databricks

Data & Backend

PostgreSQL MySQL MongoDB Redis Elasticsearch Qdrant GraphQL FastAPI Django
04

Research

// selected output
01
Demystifying Errors in LLM Reasoning Traces: An Empirical Study of Code Execution Simulation.
Mohammad Abdollahi et al.
02
Surveying the Benchmarking Landscape of Large Language Models in Code Intelligence.
Mohammad Abdollahi et al.
03
Deep-Bench: Deep Learning Benchmark Dataset for Code Generation.
Alireza Daghighfarsoodeh … Mohammad Abdollahi et al.
04
ComplexMatrixComb: Predicting Anticancer Drug Combination Dosages for Target Growth Inhibition via Complex-Number Matrix Factorization.
Mohammad Abdollahi et al.
Google Scholar
05

Community

// service & outreach
Dec 2025 — Feb 2026
Program Committee & Reviewer
MSR 2026 — View committee
  • Rapid-response reviewer for the Mining Software Repositories conference (top-tier SE venue).
  • Delivered thorough, high-quality peer reviews under tight timelines.
Mar 2021 — Apr 2021
Scientific Consultant
Datadays 2021
  • Helped design a nationwide AI challenge on Learning to Rank and recommendation systems.
May 2018 — Aug 2020
Board Member
IUT Computer Engineering Student Scientific Association (CESSA) — GitHub
  • Organized seminars, scientific talks, and coding challenges to drive student engagement.
  • Ran workshops deepening students' understanding of computer engineering fields.
06 // let's build